Regular expressions are patterns that can be used to compare text or extract information from text. For example, you can use them to check whether a log file from a program contains the string “Error” to see whether an error occurred. Or simply to see whether a string matches a certain pattern, such as an email address.
🎬 I have also created a video on this topic.
These patterns exist in many programming languages. The details of the implementations can vary, though. PowerShell and the RegEx engine used by PowerShell are based on .NET. For that reason, the .NET-specific behavior matters most here.
In PowerShell, there are several ways to use regular expressions. For example, in cmdlets, as comparison operators, or via .NET methods. In the following sections, I will show you a few of these options. I will also show you how to create the comparison patterns, meaning the actual regular expressions.
The -match operator
A simple way to make a comparison with a regular expression is the -match comparison operator. For example:
| |
This checks whether the text “Hello PowerShell” contains the string “shell”. The result is True. And this already shows the first special feature: In PowerShell, regular expressions are case-insensitive by default. That means the capitalization is ignored. However, you can also explicitly specify that you want case-sensitive matching, or explicitly say that you do not want case sensitivity. Explicitly stating that you do not want case sensitivity, even though that is the default, may seem strange at first. But it has its justification. If you do that, your code reflects a bit more clearly what you actually want.
| |
There are also the three match operators in negated form, with the addition “not”:
| |
Wildcards and quantifiers
But with regular expressions, we can do more than simply use a word or a piece of text as a pattern. There are different characters with special meanings. For example, a dot . stands for any character. And you can also specify the number of desired characters with an additional character, which in English is called a “quantifier”. Such a quantifier is appended to the previous element, meaning it always applies to the thing before it. A quantifier example is the asterisk *, which stands for any number of characters, including zero. The + symbol stands for 1 or more. The ? symbol stands for 0 or 1.
So I can also make a comparison like this:
| |
So instead of explicitly specifying “ä” here, I used the dot as a wildcard. That also returns True.
Let’s adjust it and include a quantifier.
| |
The asterisk stands for an arbitrary number. So I could also change the string so that it contains “mächtig” with three “ä” characters.
| |
Or other characters could also be matched.
| |
We can leave aside whether the last example is a proper German sentence. But this comparison also returns True because there is an m somewhere and later chtig.
By the way, quantifiers can also be used with ordinary characters, not only with special characters like the dot. For example, to check whether 0, 1, or more ä characters are present, we could do this:
| |
Note: If you want to match one of the special characters []().\\^$|?*+{}, for example if you want to check whether the asterisk symbol or a dot appears in a text, it will not work at first. To compare against such a special character, we need to escape it. We do that by writing a backslash \ before the character we want to escape. For example:
| |
This also applies to the backslash character. So to check whether a backslash symbol is present, we need to escape it with a backslash, which means there will be two backslashes in the pattern.
| |
More information about the other special characters and wildcards will follow later in the article.
The $Matches variable
When using the match operators, more happens than just returning True or False. If the comparison result is True, the $Matches variable is populated with the first match in the text. That only really makes sense when you are working with wildcards or quantifiers.
Let’s do another comparison with the match operator and then inspect the variable.
I have written the text I want to test in a rough HTML or XML style. And my pattern looks for tags named <test> </test> where any number of arbitrary characters may appear in between. Because the result is True, the $Matches variable is populated automatically.
| |
Capture groups
With capture groups, we can extract specific parts of the text. Multiple capture groups in a regular expression are also possible, but we will start with one.
Let’s stay with the example from the previous section. If I now want to extract exactly the text inside the <test> tags, the previous code is not yet ideal. But using capture groups is actually quite simple. We just need to place the part we want to treat as a capture group in parentheses (). The result of the capture groups also ends up in the $Matches variable.
| |
By the way, the $Matches variable is a hashtable. The entry with the name “0” returns the entire matched string. And if we use one capture group, it appears in the entry “1”. If we used more capture groups, there could be more entries, and they would simply be numbered further.
For example, I extract three pieces of information with capture groups here:
| |
Now I have entries from 0 to 3 in my $Matches variable. If you want to process them in code, you can access the individual entries just like any other hashtable. For example, like this:
| |
Here is an image to show visually what is being captured:
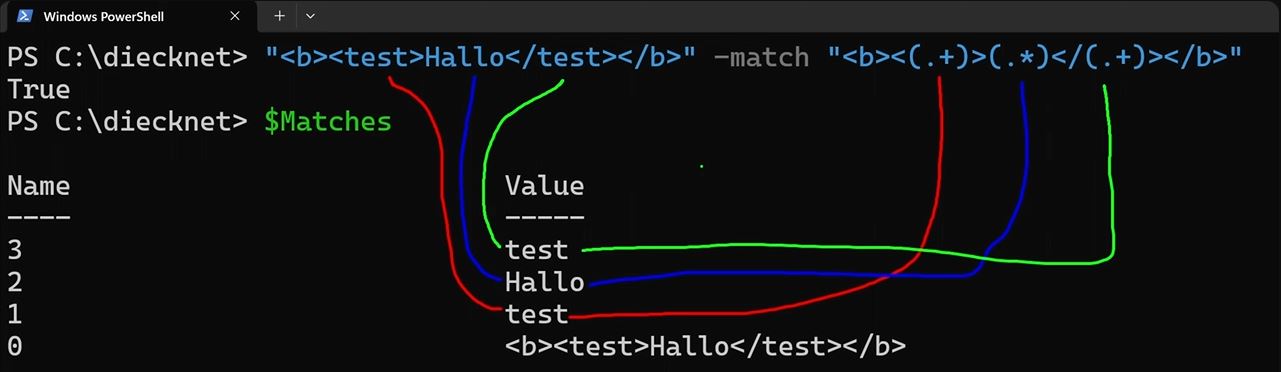
However, this numbering quickly makes the code hard to read. To make the code easier to understand, we can use named captures. That means assigning names to our capture groups. To do that, we write a ? at the beginning of the capture group, but inside the parentheses, and then provide the desired name between a less-than sign < and a greater-than sign >. The entry in the $Matches hashtable then receives the chosen name instead of a number.
| |
There is one drawback to using capture groups with the -match operator: if you want to match multiple times, it does not work. So if your regular expression matches your string multiple times, only the first result is returned. For example:
| |
The string I tested here contains two blocks with this <test> tag. But when I look in the $Matches variable, there is still only one match. That cannot be adjusted when using the -match operator. If you want to match multiple results and maybe also use capture groups, you need to use a different method, such as the .NET RegEx class.
Greedy captures
You may have noticed that the last example in the previous section contained a question mark ?. That question mark makes the regex engine non-greedy, rather than the default greedy behavior. In greedy mode, the engine tries to match as many characters as possible with the regular expression. That can lead to undesired results. For comparison, here is the result without the question mark.
| |
Special features and tips for the match operator
One special feature of the -match operator is that if you pass several objects at once as input, for example like this:
| |
Then you do not get True or False, but all strings for which the regular expression matched successfully. In that case, the automatic variable $Matches is also not populated. So if it had a previous value, it remains, and if there was no previous value, it stays empty.
My practical tips for the match operator are as follows:
If you only want to check whether a pattern applies, there is not much to worry about. Just use an
Ifstatement. That works both for a single object and for multiple objects.1 2 3 4 5$MyVariable = "Subscribe to the channel" if($MyVariable -match "abo") { # This runs if the regular expression returns True "...and like the video!" }Otherwise, you should make sure you know how many objects you are passing to
-match. It is a very common logic error not to realize that a cmdlet may return more than one object. To ensure that only one object is tested, you could, for example, limit the output to one object withSelect-Object -First 1.1 2 3 4 5$MyVariable = "User1@example.com", "User2@example.com" | Select-Object -First 1 if($MyVariable -match "user") { "User found!" # do something with the user }You can only trust the contents of the
$Matchesvariable if you really matched only one object.If you have a regular expression that matches multiple times in your string, and you want to know all matches, and maybe even extract information with capture groups, then the
-matchoperator is not suitable for that. But there are other options, for example the .NETRegExclass.
The -replace operator
With the -replace operator, the text that matches the regular expression pattern is replaced with other text.
First, a simple example where the character W and everything after it is replaced by the word PowerShell.
| |
But the -replace operator also supports capture groups. And then we can use those capture groups in the result.
| |
By the way, the $Matches variable is not populated when we use the -replace operator. If it is set on your system, it is probably from a previous comparison using the -match operator.
The -split operator
With the -split operator, you can split strings. And here too, not only simple strings can be used as separators, but also regular expressions.
A simple example:
| |
And a more complex example:
| |
The -split operator supports a few more options. I do not find them particularly interesting, and I do not have any cool examples. For that, it is best to check the Microsoft documentation: https://learn.microsoft.com/en-us/powershell/module/microsoft.powershell.core/about/about_split?view=powershell-7.4
Select-String cmdlet
With the Select-String cmdlet, a string or file content can be compared using a regular expression. Or several strings or file contents.
For example, I compare several objects here, in this case simple strings, by passing them through the pipeline to Select-Object.
| |
Of the three objects, I only get two back, because only two match the pattern. In PowerShell 7, the matching part is even highlighted in the console.
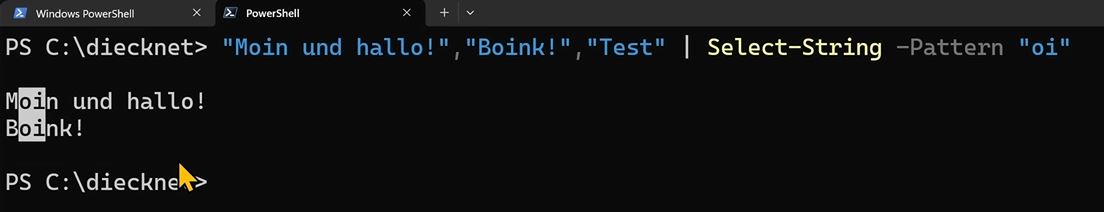
As with -match, case is ignored by default. If you want it to be considered during comparison, you can add the additional parameter -CaseSensitive. You can also reverse the check by using the -NotMatch parameter. Then only the strings that do not match the pattern would be returned.
But we could already do these things with the -match operator. What I find more interesting is the ability to check one or more files.
For example, I use this to check all files with the .log extension in the C:\diecknet directory:
| |
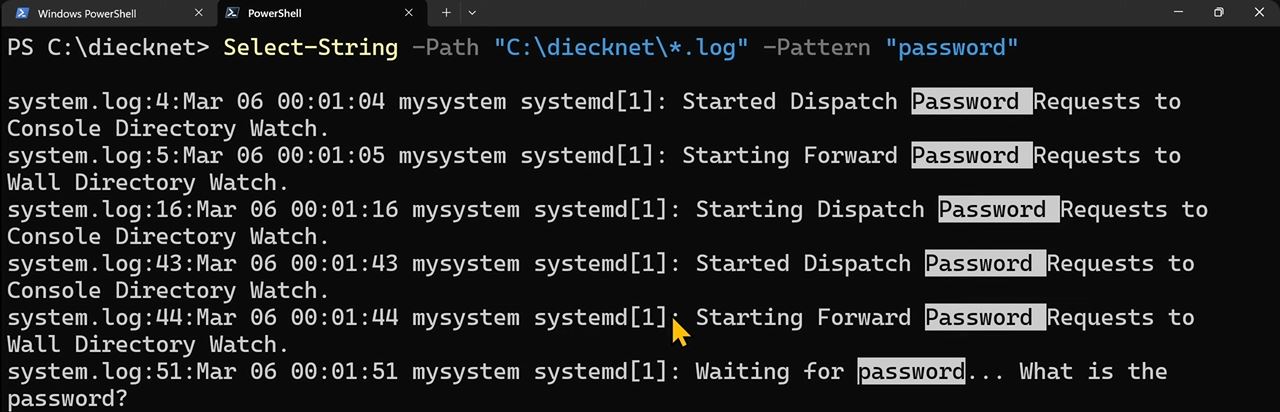
When we check one or more text files with the cmdlet, we also get information about which file the match is in and on which line.
Sometimes you want a little more information, a bit of context. For that, there is the -Context parameter. I can specify a number, and that many lines will be returned above and below the match.
| |
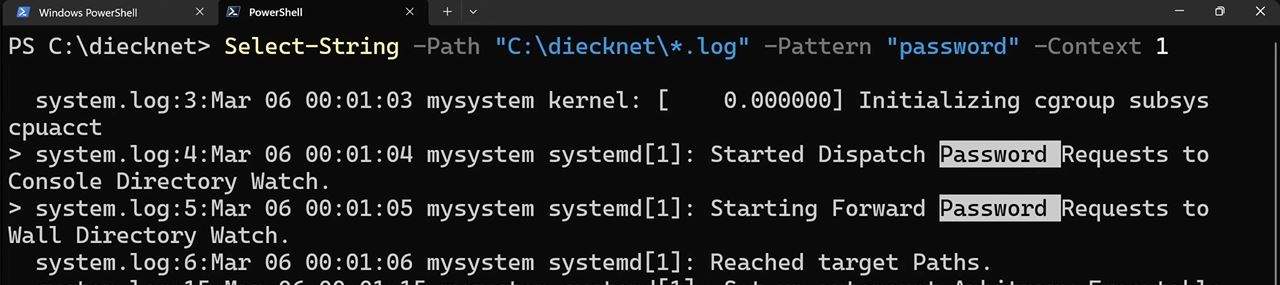
The actual line containing the match is marked with a greater-than sign >.
We can also control separately how many lines we want before and after the match. To do that, provide two numbers as the parameter value and separate them with a comma. In the following example, one line before and five after are returned.
| |
The object returned by Select-String is more than just text. In fact, we get objects of type MatchInfo here.
| |
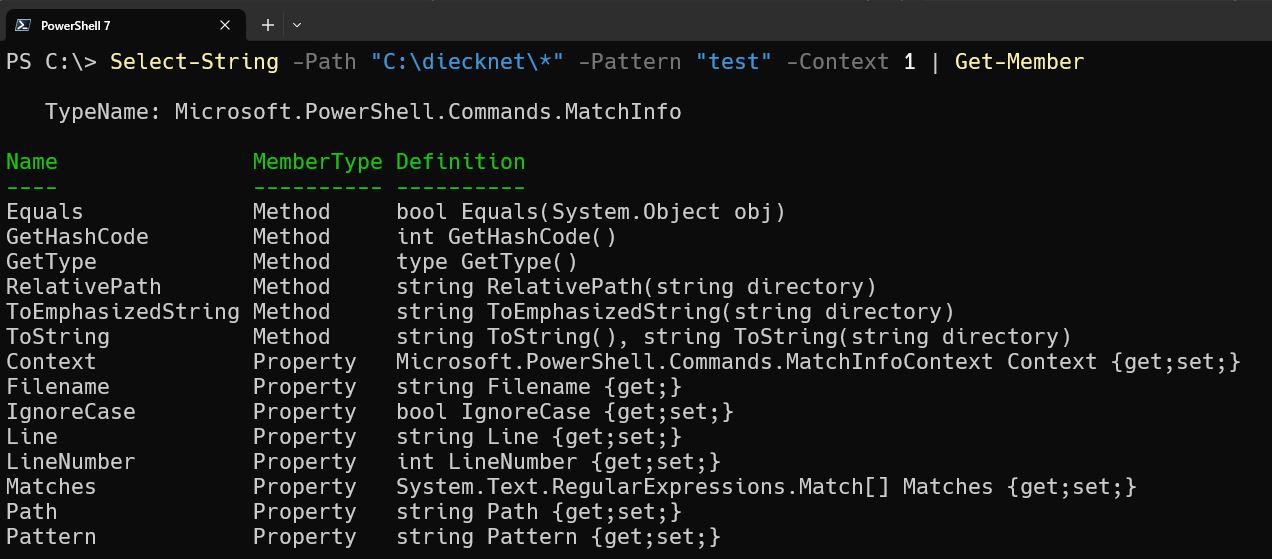
The MatchInfo object has some interesting properties that we can access in code. For example, we could also determine the exact line number of a file match in code.
| |
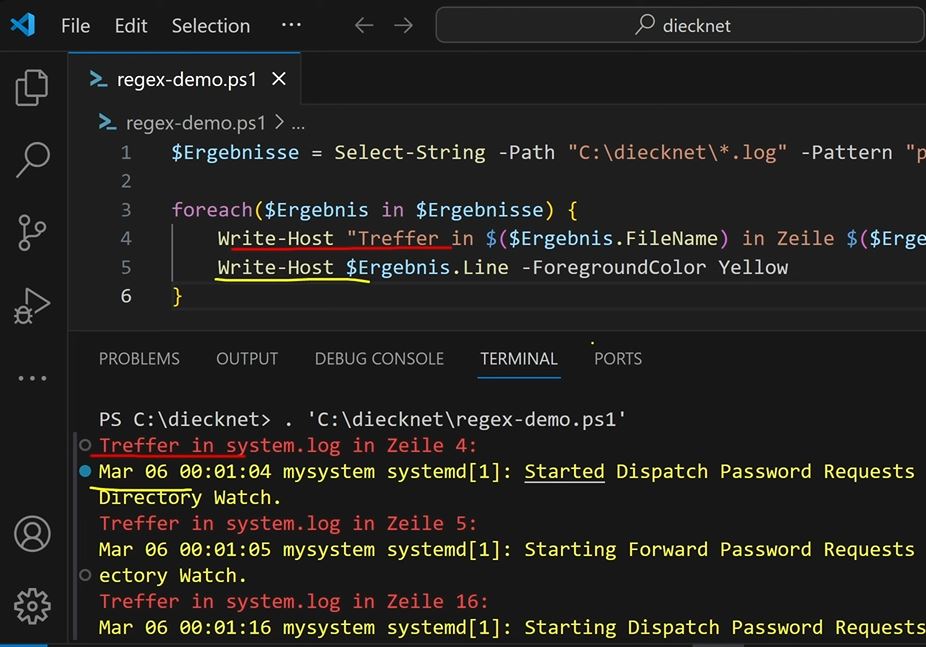
If you are interested in multiple matches in a single line, you can also enable that with the -AllMatches parameter.
| |
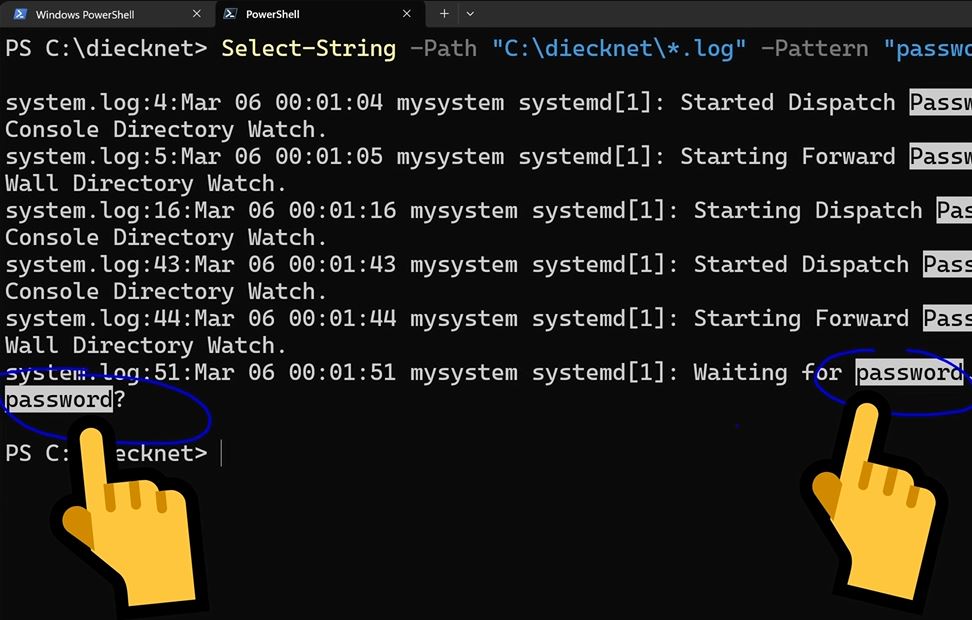
Switch statement with the -Regex parameter
The Switch statement can also use regular expressions. For that, you need to include the -Regex parameter. In each conditional block of the switch statement, you can then enter a regular expression.
| |
.NET RegEx matches
In my opinion, the most powerful way to use regular expressions in PowerShell is the .NET class RegEx. There are several ways to use the class. The simplest, in my opinion, is the following:
| |
If the regular expression matched the string successfully, you receive a match object in return. This allows you to see, among other things, that the pattern was recognized. And you can access the properties in code.
I primarily use the .NET variant when I want to extract multiple pieces of information at once using capture groups. Not just several capture groups, but when the pattern matches multiple times. For example, I have a text file with the following content (by the way, it is all on one line):
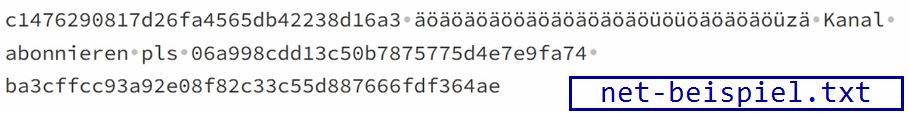
Using the following PowerShell code, I first read the text file and then check whether a pattern matches using the [regex]::Matches() method.
| |
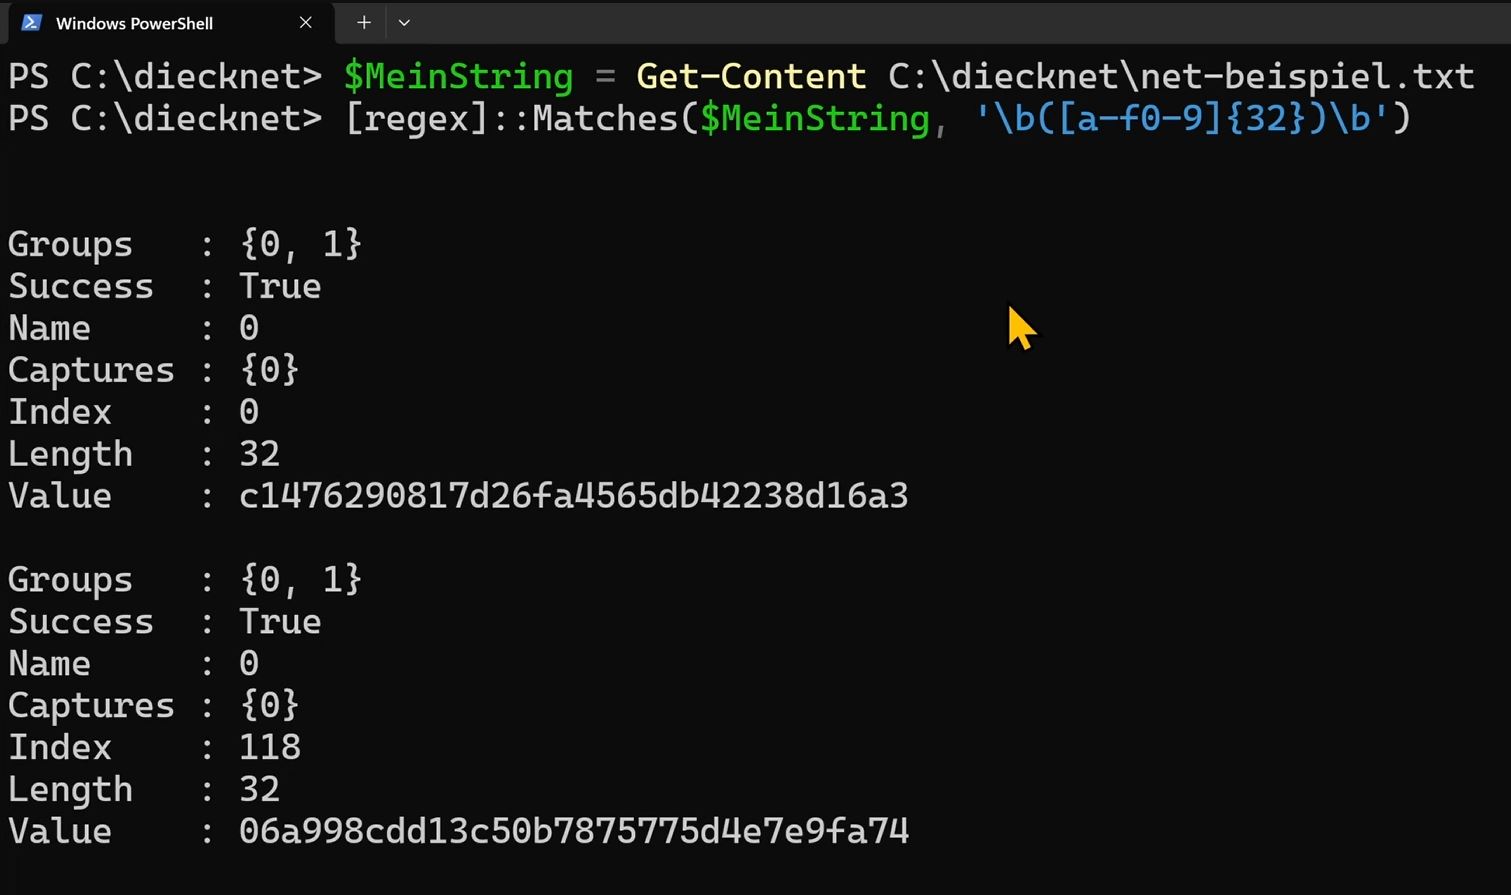
The code extracts all strings that are exactly 32 characters long and consist exclusively of hexadecimal characters. The regular expression \b([a-f0-9]{32})\b contains exactly one capture group. Because I called the Matches method from the RegEx class, I get not only the first match, but all of them.
Important: When using the .NET RegEx class, you should pay close attention to case sensitivity! Unlike the other regex options in PowerShell, it is case-sensitive by default. The following code would not find a match in the string:
| |
But the .NET [RegEx]::Matches() method supports several options. Our previous example can be extended with a third parameter to ignore case here as well:
| |
💡 You can find more options in the Microsoft documentation here: https://learn.microsoft.com/en-us/dotnet/standard/base-types/regular-expression-options?redirectedfrom=MSDN
There are also other methods in the RegEx class that can be very practical depending on the use case. Check the documentation for the RegEx class: https://learn.microsoft.com/en-us/dotnet/api/system.text.regularexpressions.regex?view=net-8.0#methods
Designing regular expressions
Okay, let’s get to how you can design regular expressions. For example, the expression from earlier: \b([a-f0-9]{32})\b
To be honest, I find regular expressions are not easy. I do not have enough experience with regular expressions that I can type them out without any help. But I usually do not even look at the Microsoft documentation for RegEx in .NET or PowerShell. Instead, I use a tool to design a regular expression. There are several free websites that let you build regular expressions in the browser and test them live against one or more strings. Recently, I have liked using RegEx101.com because it also works specifically with .NET behavior. In the past, I also used other, more general sites that were oriented more toward JavaScript. But that usually worked too. I do not know how reputable the RegEx101.com site is, so I would not put any personal data or anything critical there.
Important: On the site, you need to change the flavor to “.NET” on the left.
If you want to design a pattern, look at the “Quick Reference” section in the lower right. That explains all the possible wildcards and special characters. There is also an “Explanation” section that explains the regular expression you created. Very nice!
Conclusion
These were, in my opinion, the most important ways to use regular expressions in PowerShell. There are probably even more ways. But the basic principle should hopefully be understandable so that you can also use regular expressions in other contexts.
One more important note: If you only want to do a simple comparison, it is advisable not to use regular expressions at all. The regular expression engine has some overhead. If in doubt, test and measure the time.